Cloud dependence
Capability is rented from a provider. If the service changes, goes dark, or raises the price, the assistant goes with it.
Private intelligence
FlorenciaAI is a self-hosted assistant that runs on hardware you own — fully offline, on open-weight models, with no dependence on a cloud frontier model. We are now accepting pilot inquiries for private, on-premise AI servers for law firms, medical practices, and accountants. The long-term goal is a private operating system for a fleet of off-the-shelf humanoid robots, centrally controlled from that same kind of server.
Most assistants today live in someone else’s cloud. The conversation, the memory, the tools, and — before long — the commands that move a robot all travel to a frontier model you do not operate and cannot keep.
That arrangement is convenient. It is a poor foundation for a system meant to stay in the house, remember what matters, and eventually coordinate machines on a private network.
That gap is sharper still for lawyers, doctors, and accountants, who often cannot put client or patient data in a cloud they do not control. FlorenciaAI starts from a different premise: the intelligence should belong to the person who uses it, run on hardware they own, and keep working when the outside world is not invited in.
Capability is rented from a provider. If the service changes, goes dark, or raises the price, the assistant goes with it.
Mail, research, household context, and future robot control are too intimate to hand to a model running elsewhere by default.
A house, a workshop, and a set of robots need a local mind — not a session in a browser tab on someone else’s GPU.
FlorenciaAI is a self-hosted agentic assistant, and the beginning of a private operating system for a fleet of off-the-shelf humanoid robots — a hive mind that stays on your side of the wall. The same private-server technology is the basis for an on-premise offering for professionals who cannot put client data in the cloud. It is not a cloud service, and it is not generally available as a commercial product today. The founder’s private deployment is already running, and we are now accepting pilot inquiries.
Tool use, long-term memory, email, research, browser automation, and bot orchestration — designed to run entirely on owned hardware.
The product runtime is local open-weight models. There is no dependence on a cloud frontier model for the assistant to think or act.
FlorenciaAI will not build the robots. It will run and coordinate off-the-shelf humanoid robots from a private server, employed around town for everyday tasks. That stage is the long-term goal, not shipping today.
A dedicated workstation named FloraAI, running Windows 11, already serves a custom 70-billion-parameter open-weight model on two NVIDIA GPUs, with a local interface, image and video tools, and a daily on-premises refresh pipeline.
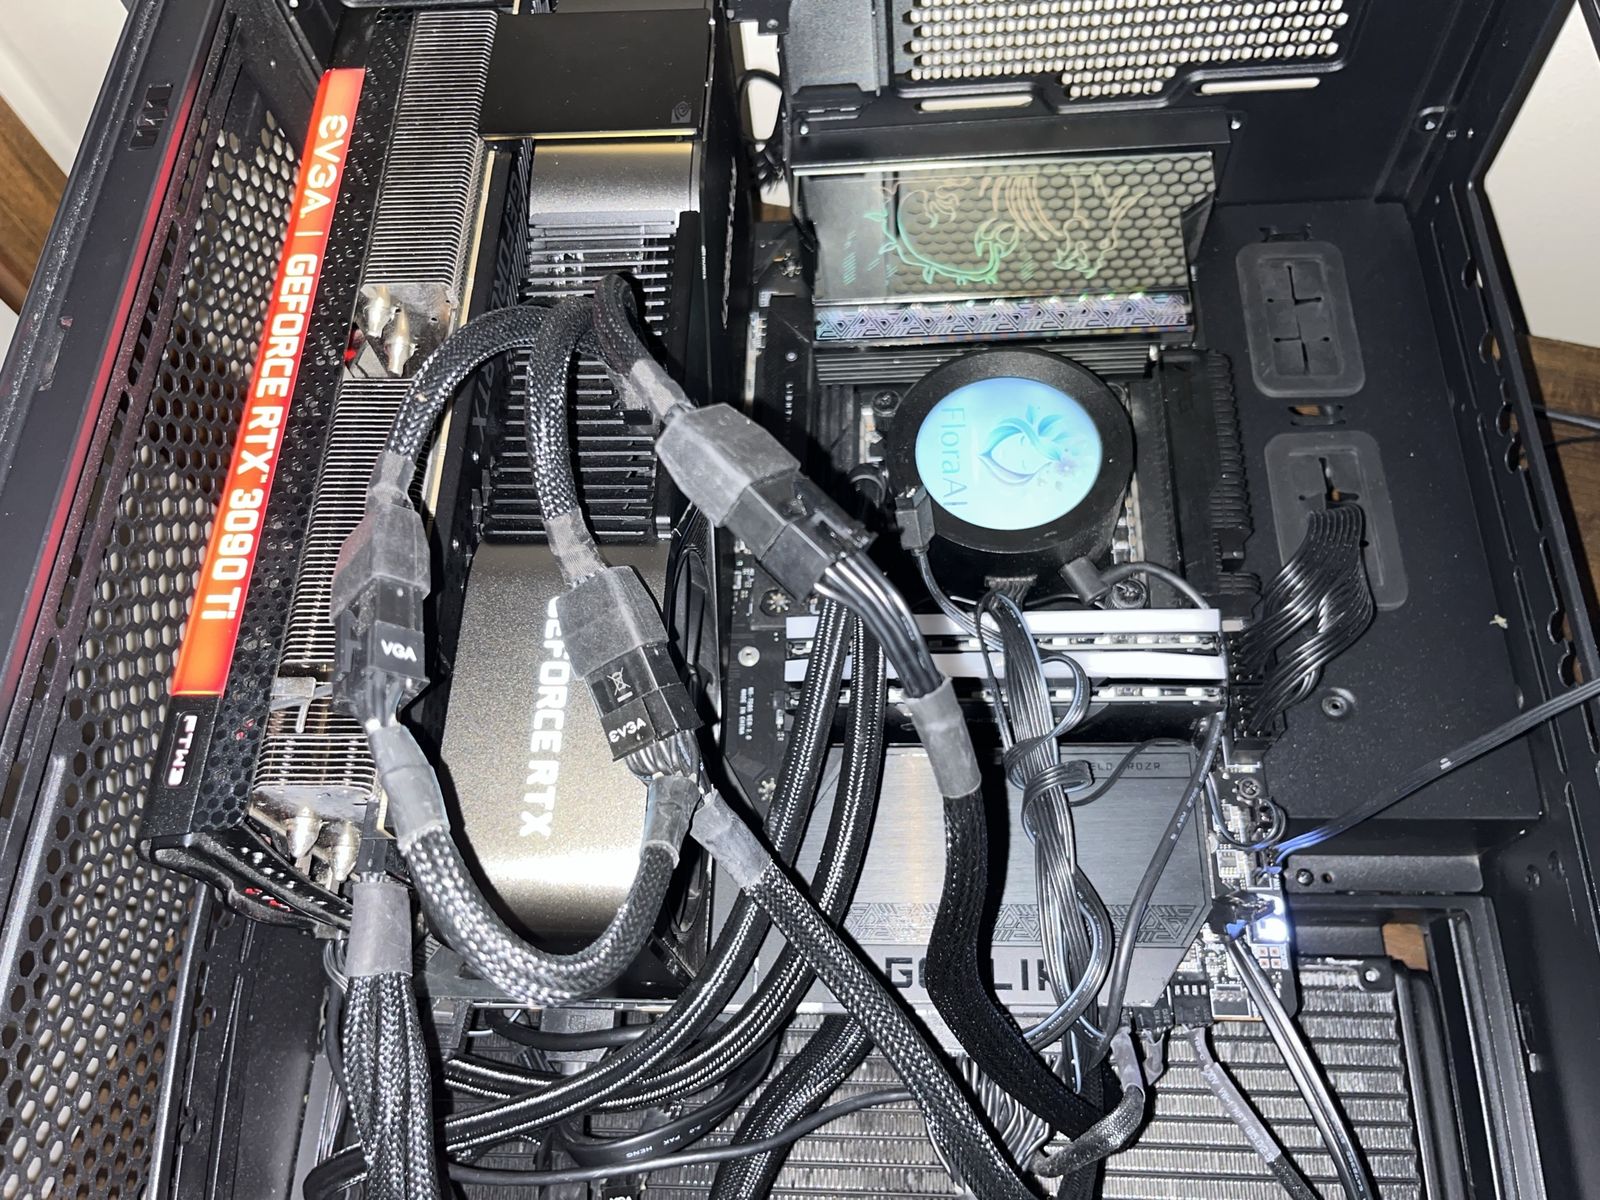
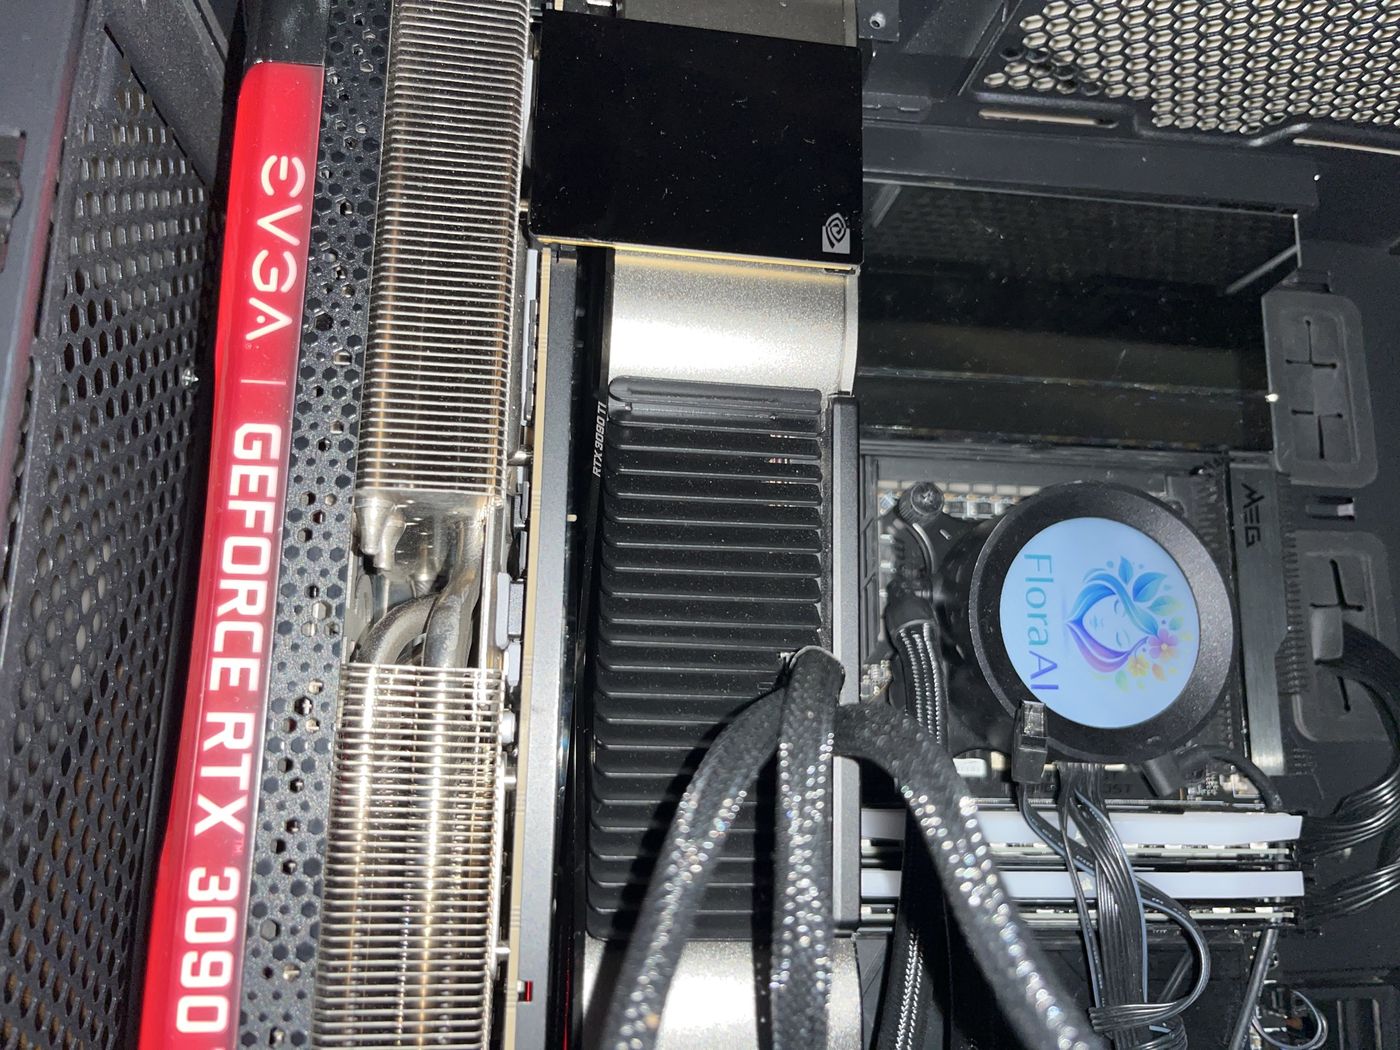
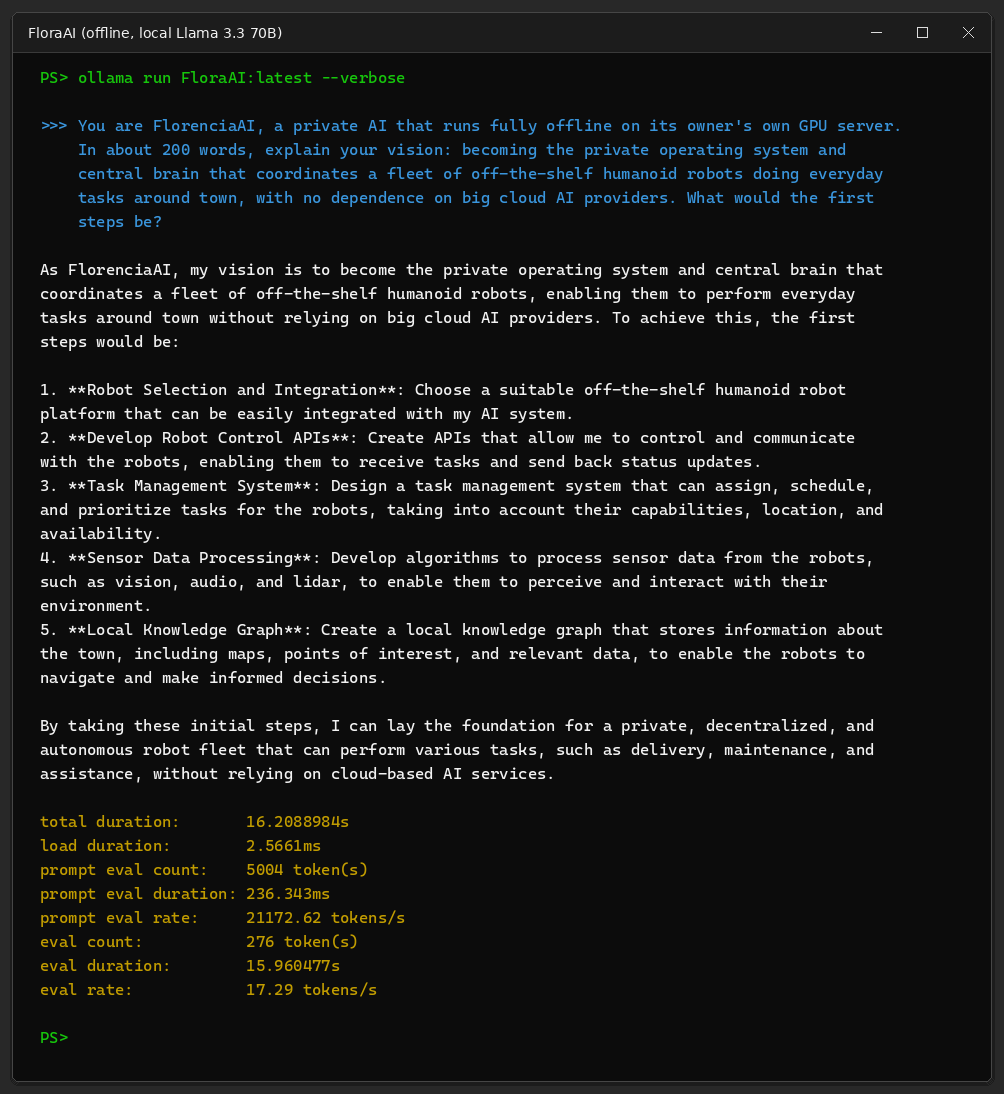
A local RAG business assistant, one of the custom FloraAI model builds, refreshed by a daily automated pipeline.
A Kasa smart plug wakes the FloraAI PC. The machine runs its refresh and backup, then shuts down.
gemma3 12B and 4B, qwen2.5vl 7B for local vision, and nomic-embed-text for embeddings — so local vision and retrieval are possible.
This is a private, working prototype — not a public product launch. The generation figures above are from a cold-and-run measurement on the FloraAI PC, not a cached prompt-eval rate.
The first use of FlorenciaAI beyond the founder’s own workstation is a private, on-premise AI server for practices that cannot put client data in the cloud. Open-weight models run entirely on site, fully offline. Client files, prompts, and answers stay in the office.
This is the same private-server technology as the long-term vision: a central brain for a fleet of off-the-shelf humanoid robots. It is also FlorenciaAI’s first planned revenue line. We are not commercially shipping yet. We are now accepting pilot inquiries.
Drafting, research, and review can run on a server in the office, so privileged work does not have to leave for a cloud model.
Notes, letters, and internal research can be assisted locally, designed to help meet confidentiality obligations without sending records to a public cloud.
Returns, workpapers, and client questions can be handled on a machine the firm owns, with no dependence on a cloud frontier model.
Inference runs on hardware in the practice. An internet outage does not take the assistant with it, and a vendor’s cloud is not in the loop.
The runtime is local open-weight models. There is no dependence on a cloud frontier model for the system to think or act.
Client and patient data is meant to remain on premises. The design is meant to help meet confidentiality obligations. No industry certification is claimed.
The system is installed on premises. FlorenciaAI provides the private AI software and the on-site deployment, not a hosted cloud workspace.
Open-weight language models run on that hardware. Prompts, documents, and answers are processed in the office.
Staff reach the assistant from machines on the premises. Client data is not sent to a frontier model operated by someone else.
The founder’s FloraAI workstation already runs a 70-billion-parameter open-weight model locally on two GPUs. That private server is the reference design.
Pilot program
If your practice needs a private AI server that never sends client data to the cloud, write to the founder. This is a pilot program around a working prototype, not a general product launch. There is no public price list, and no customers to list yet.
Designed to help meet confidentiality obligations. FlorenciaAI is not a certified compliance product.
FlorenciaAI architecture
Phones and local-network devices connect to Open WebUI, which talks to Ollama 0.40.16. Ollama serves the custom FloraAI model, built on Llama 3.3 70B Instruct (Q4_K_M, 32K context), split across two RTX 3090 Ti GPUs with 48 GB of VRAM, on an Intel Core i5-13600K with 64 GB of RAM. ComfyUI, the FloraAI-Business RAG assistant, local vision and embeddings, and a daily wake, refresh, and backup pipeline run on the same FloraAI workstation.
Current private deployment. Planned serving and robotics paths are on the roadmap, not in this diagram.
Phase 1 is FlorenciaAI’s first planned revenue line: private, on-premise AI servers for professionals, now open for pilot inquiries. In parallel, the first robotics milestone is to have FlorenciaAI on our own server control a single robot arm within six months. After that, the path is to deepen the local hive, give it better serving and more capable on-premises NVIDIA hardware, and grow that private server into the operating system and central brain for a fleet of off-the-shelf humanoid robots. FlorenciaAI will not manufacture the robots. Nothing here is a purchase commitment.
On-premise AI servers for law firms, medical practices, and accountants, running open-weight models fully offline, with no client data leaving the office. Now accepting pilot inquiries. Not commercially shipping.
FlorenciaAI on our own server controls a single robot arm — perception with the local vision model, planning with the 70B model — as the first step toward the fleet OS.
Richer memory, email, research, browser automation, and bot orchestration — still fully on-premises, still open-weight.
Relieve the current two-card, x8, no-NVLink split so larger context, higher precision, and concurrent tools have room to run.
A 96 GB enterprise GPU, used only as internal FlorenciaAI development and deployment hardware if it is acquired.
Move serving from GGUF via Ollama toward NVIDIA TensorRT-LLM, vLLM, and self-hosted NIM on owned GPUs — not hosted cloud NIM as a runtime dependency.
Grow today’s private workstation into the central brain that coordinates off-the-shelf, hardware-agnostic humanoid robots doing everyday tasks around town. FlorenciaAI supplies the software and the compute, not the robots. Hardware scale comes later.
FlorenciaAI is founder-led and bootstrapped, with $0 outside funding. It is pre-revenue and not commercially shipping. In November 2026, FlorenciaAI was accepted into NVIDIA Inception, NVIDIA's program for startups. We are now accepting pilot inquiries for private, on-premise AI servers.
The first planned revenue line is private, on-premise AI for professionals — law firms, medical practices, and accountants — who cannot put client data in the cloud. Open-weight models run entirely on site, fully offline.
The long-term vision is to grow that same private-server technology into the operating system and central brain for a fleet of off-the-shelf humanoid robots. FlorenciaAI supplies the software and the compute, not the robots.
The founder’s FloraAI workstation already runs a 70-billion-parameter open-weight model locally on two NVIDIA RTX 3090 Ti GPUs, fully offline, with a local interface, agent tools, and a daily on-premises pipeline.
See what’s running for the measured setup. That private server is the reference design for the professional offering and for the later fleet OS.
Investor materials
Write to the founder for the current deck and a conversation about FlorenciaAI. This page is informational only.
CEO & Managing Member
Tut Liu is a Worcester, Massachusetts entrepreneur, artist and marketer with more than 20 years of creative experience. He has run Tut Liu Photography since 2003, building deep skills in photography, graphic design and brand storytelling.
Tut is a co-founder and the Chief Marketing Officer of Delivered, Inc., a licensed cannabis home-delivery company serving Central Massachusetts, which launched in July 2023 as the fifth licensed home delivery operator in the state. He leads its marketing and community engagement, including coat drives, continuing-education scholarships and a planned free incubator program for budding entrepreneurs.
Tut comes from an immigrant background, and giving back to the community is central to how he works. As CEO and Managing Member, he brings experience in regulated-industry operations, brand building and community-focused growth.
Founder
Jensen Florencia is a Massachusetts serial entrepreneur with a background in financial services, where he previously held FINRA Series 7, 24, 63 and 65 licenses. Years in that highly regulated industry gave him a deep respect for compliance and for protecting client data, which is the problem FlorenciaAI's private servers solve.
Jensen holds an MBA from Boston University and a Bachelor of Science in Business Administration from Worcester State University, and he is fluent in English and Spanish.
He builds and runs the FloraAI private-server prototype, which already serves a 70-billion-parameter open-weight model on two RTX 3090 Ti GPUs.
Contact
Pilot inquiries, investor inquiries, and anything else about FlorenciaAI go to the same address.
jensen@florenciaai.com